LLMday

Large Language Models, Agents & AI Systems

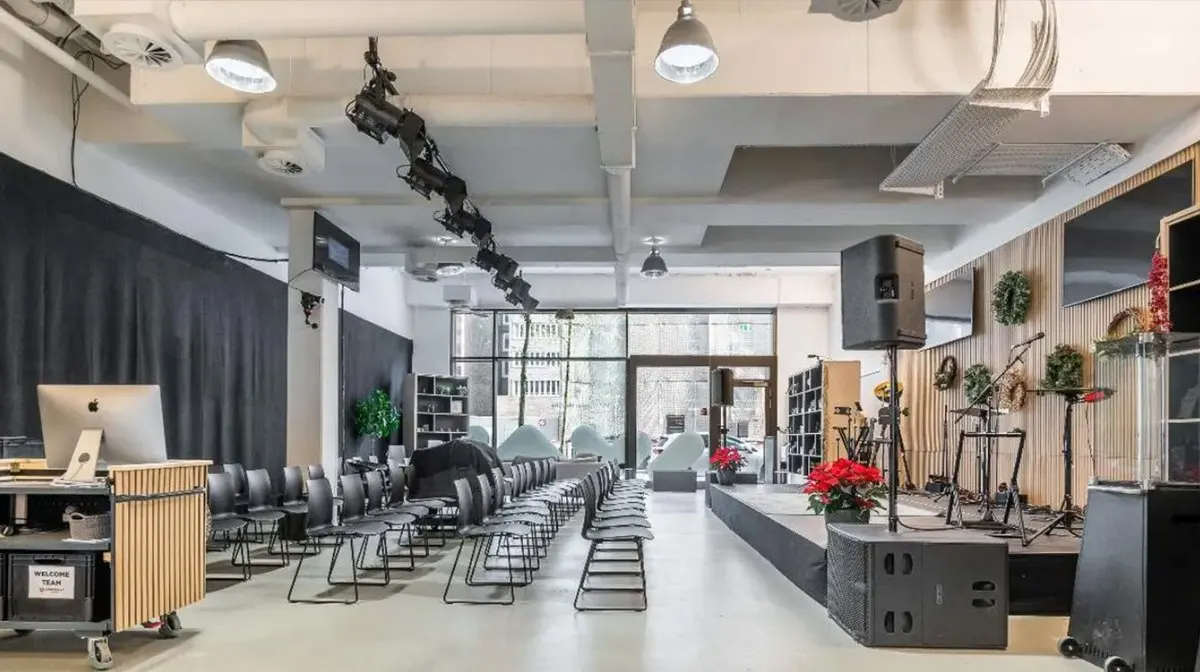
November 18, 2026 House of AI, Hamburg, Germany

1
Day
10+
Speakers
1
Track
100+
Attendees

LLMday is a worldwide series of community events for engineers building with large language models, AI agents and machine learning. Across cities around the world, we bring together practitioners working on AI-powered products and systems to share real-world experience, learn from each other and explore how software engineering is changing in the age of AI.

Companies presenting:

Adjoe, DKB Code Factory, HeyBreez AI, justtrack, Kvick, Lavan Labs, Lioren, MeloMar-IT, moebel.de Einrichten und Wohnen, MoinMeister, Netlight Consulting, OMR Reviews, ScyllaDB, vCluster Labs

Topics so far:
LLMOps & AI Infrastructure

Event Starts In:

Tickets

Schedule

November 18, 2026 • single track • 9AM - 6:30PM • Hamburg, in‑person
View
Main room

09:00

Gabriel Awad

KeynoteDesign, Product, Engineering: What Our AI-Driven Design Workflow Fixed and What It Broke

justtrack GmbH
What changes when a design team runs its whole workflow through an AI agent? We rebuilt ours at justtrack as scoped skills: requirements, research, design, critique, pre-handoff check. One feature now goes from ticket to clickable prototype in a day, whatever its size. That prototype replaced the Figma file as the thing product owners react to, so feedback lands earlier and the requirements document updates itself from what gets decided. Engineering receives a design that has been through a mechanical check before anyone opens it. But generating a screen is the easy part. Making it match an existing design system, survive a review, and arrive in a form engineering can build takes more than a prompt. This session is also about the parts that did not work: what happened when we handed Claude Design our design system, why the obvious fixes failed, and what the handoff to developers looks like when the artefact itself is in question. What you'll take away: Why one agent with scoped skills beats one agent per role How to feed a design generation with real inputs: the ticket, the requirements, industry patterns, and your own user research Why attaching a design system file or a component library produces worse output than you expect, and what works instead How to give your agent a written set of UX principles so its design critique becomes usable instead of noise The open question: Figma file or working prototype as the artefact engineering receives... Read more

09:30

Coffee break

Main lobby

10:00

Marcel Koert

The Code Was the Easy Part: Building Spaghetti Code Foundry

MeloMar-IT
The Code Was the Easy Part Building Spaghetti Code Foundry We started building Spaghetti Code Foundry with a simple vision: place a label on a GitHub issue and let AI agents plan the work, write the code, run the tests, review the result and prepare it for delivery. The first design treated the factory as a pipeline for producing code. We quickly discovered that writing code was the easy part. The real engineering challenges lived around the pipeline. Stories had to be clear and small enough to build. Parallel agents needed coordination. Approvals became queues. Status information had to remain trustworthy after partial failures. Retry loops needed brakes. Test suites became production bottlenecks. The factory needed monitoring, recovery procedures, capacity limits and an operating model of its own. At one point, the Foundry became so effective at improving itself that it stopped delivering work for the product it was supposed to support. This talk shares eleven practical lessons learned while building and operating an open-source AI software factory. It covers the failures that changed the architecture, the features those failures produced and the trade-offs involved in moving from assisted coding toward autonomous software delivery. Along the way, we will look at how Spaghetti Code Foundry turns issues into coordinated flows of questions, planning, implementation, testing and review—and why increasing autonomy makes visibility, governance and operational discipline more important rather than less. The central lesson is simple: A software factory is a coordination and trust problem with a coding step in the middle. The talk is intended for software engineers, platform teams, SREs, engineering leaders and anyone experimenting with AI agents in real software-delivery workflows.... Read more

10:30

Piotr Zaniewski

Your Platform Already Has AI Users

vCluster Labs
AI tools already run inside your organization: MCP servers over internal docs, RAG services over company data, and agents that call other systems. Agents use the same platform APIs your developers do, but they need different things: a finite context budget, no memory between sessions unless the platform keeps it, an identity of their own, and a human before they write. Without shared guardrails, every team solves isolation, data access, and policy on its own, and the platform team becomes a ticket queue. This talk applies platform engineering to AI tools: paved roads where a team brings its tool and the platform provides an isolated runtime with guardrails in place from the start. We cover: - Roads by risk class: a read-only docs server, a data tool, an agent with write access, and a GPU workload each get a different baseline - Isolating teams on a shared cluster with virtual clusters - A live demo: a team ships a real MCP server without writing a security rule, the road refuses an unsafe deployment, and another team's AI assistant uses the tool from a plain-English request - A maturity model for agent platforms, from ad hoc API keys to agents that earn wider permissions.... Read more

11:00

Ebrahim Mirsafian

Testing Voice When Your Coding Agent Can't Hear

Lavan Labs Ltd
We build a voice AI co-worker that lives inside web apps, and we build it with coding agents like Claude Code. The problem is that voice isn't something a coding agent can test by itself, because it can't hear. It writes the change and runs the tests, but it has no idea if the voice still works. And for voice AI it's not only about whether sound comes out or the transcript is right. It also has to get what the user wants and call the right function, so the thing actually happens in the app, even when someone's tapping on the desk or the network drops. So we built a twin. It role-plays a user with a goal and talks through a fake microphone into the real voice pipeline. The whole session comes back as text the coding agent can read. A test only passes if the right action really happened in the app, not because the answer sounded right. A run costs one or two cents, so the coding agent can run it after every change. I'll run it live and show what it caught, for example a reconnect that killed the session 11 seconds in, which in the end was triggered by our own test tool. I'll also show what it can't catch, like the day our German sessions went silent while every transcript looked fine. Hopefully you leave with a way to test your own voice features without listening to every change.... Read more

11:30

Ivan Vokhmin

From RAG to memory decay: engineering a memory for chatbots and beyond

moebel.de Einrichten und Wohnen GmbH
Every conversation with an AI starts from zero. To help users, we have to populate an LLM's context with correct information, in the right amount, at tolerable latency. We explore: Populating the context: static knowledge injection, RAG and the agentic loop. Types of information — and which database each one needs. Dealing with stale context in vector knowledge bases: decay and priority metrics on the reranking phase — or pushed inside the HNSW KNN walk itself. Bypassing embedding context limitations with semantic centroids. This is an engineering talk with learnings from different use cases, from local chatbots to large e-commerce applications. Forgetting is not a bug. It's a design choice.... Read more

12:00

Hello Hamburg!!! - short Intro to LLMday

Main room

12:10

Lunch & networking

Main lobby

13:00

Jan Kleine-Klatte

Testing AI Agents Like Self-Driving Cars

MoinMeister
Getting an autonomous driving system to work in a demo is easy; getting it reliably into production is where the real engineering happens. Jan spent nearly a decade on exactly that, building autonomous driving systems that had to pass large-scale cloud simulation, scenario-based testing and safety assurance before they reached the road. In this talk, he shows how he applied those lessons to the MoinMeister Phone Agent, an AI voice assistant that answers calls and books appointments for car repair shops, from building a scenario library and regression evals to testing with simulated callers. Attendees will leave with a practical playbook for taking LLM agents from impressive prototype to a system real businesses trust with their phone line.... Read more

13:30

Attila Toth

The hidden infra behind "For You" pages: Real-time AI personalization

ScyllaDB
AI personalization for apps with a large and global user base is a difficult engineering challenge. Global companies like Tripadvisor, Medium, and ShareChat depend on highly available, low-latency AI infrastructure to deliver hotel recommendations, "For You" feed items and relevant short-form video content. In this talk, we cover the underlying systems that power these user facing recommendation use cases. - Running real-time model inference with millisecond latency - Setting up a centralized feature store that feeds both training and serving - Leveraging OSS feature store frameworks and tools - Best-practice data modeling approaches for online inference to minimize latency - Cost-effective utilization of cold/object storage, hot caches, and low-latency databases for model training and user-facing inference - Meeting strict SLAs (p90, p95, p99, etc) By the end, attendees will learn how to design AI infrastructure that serves fresh features in milliseconds. They will also see real data models, latency numbers, and cost trade-offs from three production systems.... Read more

14:00

Philip Laine

It’s Time to Serve 💅 AI Models

Kvick
If you’re being challenged by deploying artifacts for AI workloads on a platform built for lightweight, ephemeral containers, you’re not alone. Model deployments are coming with 20-minute cold start times, nodes OOMing, and downloads restarting due to pod failures. We’ll unpack all the solutions out there, starting with level 1 - implementing an in memory caching solution. As we progress the levels get more intricate, such as leveraging kServe cluster storage containers and HuggingFace XET proxies. The final level includes ModelPack, Harbor, and Spegel - which can either supercharge or super-nerf your approach. To finish the game we will answer the most important questions of them all: “Can model artifacts be converted into OCI artifacts, and if so, at what cost?” You’ll leave knowing which solution can be implemented into your platform today, and the cheat codes to complete the next levels of solutions. It’s dangerous to deploy model artifacts alone, take our lessons with you.... Read more

14:30

Shekhar Khandelwal

From Chatbot to Company Brain

Adjoe
A chatbot can answer general questions. It can't tell you why a key metric dipped last week, because it can't see your data, tickets, documents, or code. This talk shows how we turned a generic chat assistant into a "company brain": one place where employees ask questions in plain English and get answers drawn from the systems they already use. We start with a chat interface that can use any large language model. We then add three building blocks: - Connectors to internal data, documentation, ticketing, and communication systems, built on an open standard (the Model Context Protocol). - Skills, which are centrally maintained, reusable bundles of domain knowledge. - Tools such as web search and code execution. Wiring these up by hand in every chat doesn't scale, so we package them into pre-built agents. Specialist agents each own one domain, and an orchestrating agent routes every question to the right specialist. Connectors run under each user's own identity and are read-only, so the assistant only sees what the person asking is allowed to see. You'll leave with a practical blueprint: how to layer models, connectors, skills, and agents, how to handle permissions, and what to watch out for when rolling it out company-wide.... Read more

15:00

Networking & sponsor crawl

Main lobby

15:30

Faris Qatawneh

Voice AI Is an Operations Problem: How We Ship and Run Agents at Scale

HeyBreez AI
Most voice AI conversations focus on models, voices and latency. In production, those are rarely what decides success. The harder problem is operational: how agents are built, tested, released and kept healthy once real customers start calling. This talk shares the operating model HeyBreez uses to deliver inbound and outbound voice agents for banks, telcos and e-commerce companies across the Middle East, in multiple Arabic dialects. It covers how builder teams are organized to balance speed and quality, the QA process every agent passes before going live, and how calls are reviewed and agents improved week after week. It also covers when an agent should hand off to a human, and the metrics that separate an agent that sounds good from one that delivers results. Attendees will leave with a practical framework for running voice AI as an ongoing operation rather than a one-time project, and a clear view of the failure points most teams discover too late.... Read more

16:00

Miroslav Dzunic

Build Your Own Agentic Factory: Agents Still Need a Definition of Done

DKB Code Factory GmbH
Your agent says it’s done. It isn't. I spent 15 years hearing that from humans. In 2013 I worked on building a browser document editor. A decade later the product died, so I rebuilt it without writing code, in an agentic factory made of the practices everyone calls essential, then quietly skips. Two products from the Factory so far: an office suite with .docx round-trip and track changes, and ReaLLM, a space RPG you can play on your phone if this talk gets boring. Together, about 1,700 commits, 1,700 end-to-end tests and 460,000 lines of product code. You will learn to: 1. Define "done" so an agent can’t talk its way past it, with checkable acceptance criteria, a read-only reviewer, and a merge left to a script, never a model. 2. Turn your backlog, story points, WIP limits, code review and CI/CD into agent stages, using tools you already have. 3. Decide what humans still own: keep GitHub credentials from agents, never let the factory change its own gates, and count every human touch.... Read more

16:30

Kristaps Pluto

The Untrusted Web: Rethinking Security in AI Systems

Independent/Freelance
As AI assistants and agentic systems increasingly interact with emails, websites, social media, online reviews and digital documents, a new attack surface is emerging: the manipulation of AI systems through seemingly harmless external content. Malicious actors can exploit indirect prompt injection by embedding instructions in content that an AI system is asked to read, analyse or process. Unlike traditional scams that target people directly, these attacks attempt to manipulate the AI assistant acting on a user's behalf, potentially influencing its decisions, revealing sensitive information or triggering unintended actions. This talk explores how everyday online interactions can become attack vectors for AI-powered systems. It examines why these threats become particularly concerning when AI systems have access to personal information, communication channels and external tools, and discusses practical approaches to reducing risk through trust boundaries, permission controls, input handling and human oversight.... Read more

17:00

Lior Oren

We Know How to Run the Harness - But Do We Know Who?

Lioren
Over the last year, we have seen many examples of development harnesses and agent factories. Many of us now use them, and each organisation has its own version. We know how to run them. We are less clear about who should own them, who actually feels responsible for them, and how developers should work with them. This talk looks at the organisational design behind the harness: how it represents stakeholders, reflects the organisation’s structure, and receives and uses context.... Read more

17:30

Pedro Treuer

Agentic Development - What works for me

Netlight Consulting GmbH
From Idea to PoC: Spec-Driven Development with LLMs How can LLMs help turn an app idea into a working proof of concept? In this talk, Pedro shares how he used agentic coding and spec-driven development to build a PoC for a startup. From shaping the initial idea and defining the architecture to implementing the app. Through practical examples, he walks through his workflow, shares tips for guiding coding agents, and showcases useful tools along the way. He wraps up with lessons learned: what worked, what didn’t, and what he would do differently next time.... Read more

18:00

Izabel Cvetkovic

Hallucination Gating for multi-agentic systems

OMR Reviews
RAG reduces hallucinations, but it doesn't stop them. A model can retrieve the right documents and still state something they never say. For example, it might name a software product's pricing tier that appears nowhere in the retrieved data. To a user comparing tools before a purchase, a confidently wrong price looks exactly like a correct one. This talk presents the grounding gate built into OMR Reviews' multi-agent AI Buying Assistant. Before an answer reaches the user, the gate extracts its claims, and an LLM judge checks each one against the retrieved data. The talk covers how claims are extracted and matched to sources, where LLM-as-a-judge verification holds up and where it fails, and the trade-offs between latency, cost and strictness. The gate is one part of a larger evaluation package that includes LLM-judged regression tests, automated QA on every merge to staging that checks tool calls and trajectories, and post-hoc issue detection on live traffic. The talk closes with how these layers work together.... Read more

18:30

Wrap up

Scan each other's QR codes & head to a nearby pub!
Main room
  1. 09:00
  2. 09:30
    Coffee break
  3. 10:00
  4. 10:30
    Your Platform Already Has AI Users
    Piotr Zaniewski · vCluster Labs
  5. 11:00
    Testing Voice When Your Coding Agent Can't Hear
    Ebrahim Mirsafian · Lavan Labs Ltd
  6. 11:30
    From RAG to memory decay: engineering a memory for chatbots and beyond
    Ivan Vokhmin · moebel.de Einrichten und Wohnen GmbH
  7. 12:00
    Hello Hamburg!!! - short Intro to LLMday
  8. 12:10
    Lunch & networking
  9. 13:00
    Testing AI Agents Like Self-Driving Cars
    Jan Kleine-Klatte · MoinMeister
  10. 13:30
  11. 14:00
    It’s Time to Serve 💅 AI Models
    Philip Laine · Kvick
  12. 14:30
    From Chatbot to Company Brain
    Shekhar Khandelwal · Adjoe
  13. 15:00
    Networking & sponsor crawl
  14. 15:30
  15. 16:00
  16. 16:30
    The Untrusted Web: Rethinking Security in AI Systems
    Kristaps Pluto · Independent/Freelance
  17. 17:00
  18. 17:30
    Agentic Development - What works for me
    Pedro Treuer · Netlight Consulting GmbH
  19. 18:00
    Hallucination Gating for multi-agentic systems
    Izabel Cvetkovic · OMR Reviews
  20. 18:30
    Wrap up

Speakers

Attila Toth
ScyllaDB
Ebrahim Mirsafian
Lavan Labs Ltd
Faris Qatawneh
HeyBreez AI
Gabriel Awad
justtrack GmbH
Ivan Vokhmin
moebel.de Einrichten und Wohnen GmbH
Izabel Cvetkovic
OMR Reviews
Jan Kleine-Klatte
MoinMeister
Kristaps Pluto
Independent/Freelance
Lior Oren
Lioren
Marcel Koert
MeloMar-IT
Miroslav Dzunic
DKB Code Factory GmbH
Pedro Treuer
Netlight Consulting GmbH
Philip Laine
Kvick
Piotr Zaniewski
vCluster Labs
Shekhar Khandelwal
Adjoe

Venue

House of AI

Hongkongstraße 2
20457 Hamburg, Germany

Sponsors & Partners

Want to become a sponsor? Get in touch!
Let's talk!
We'll email you and share prospectuses for relevant events.
We'd like to (one or more)
Pick at least one
Conferences (one or more)
Pick at least one
Regions (one or more)
Pick at least one
Budget
Pick one