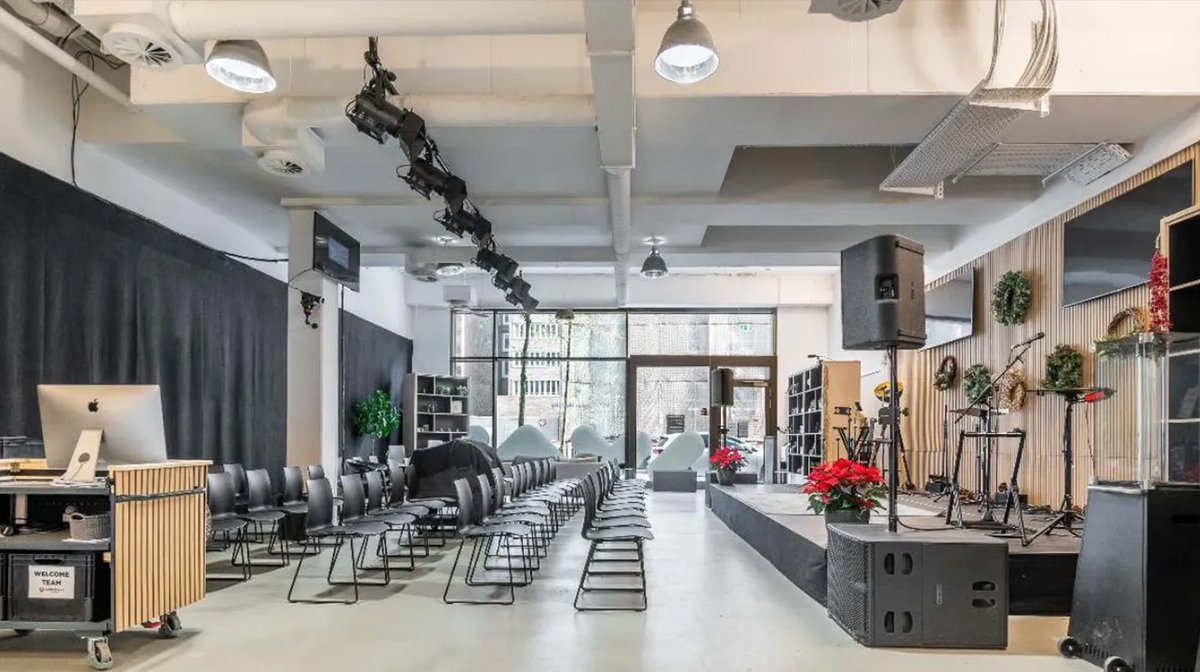
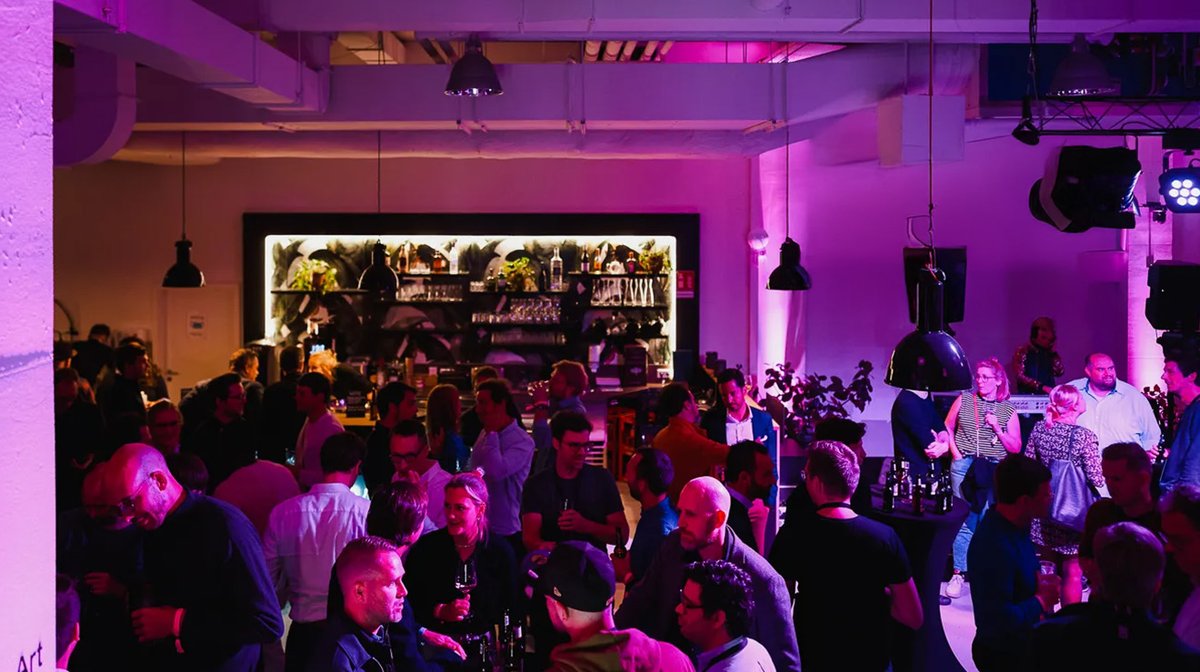
LLMday is a worldwide series of community events for engineers building with large language models, AI agents and machine learning. Across cities around the world, we bring together practitioners working on AI-powered products and systems to share real-world experience, learn from each other and explore how software engineering is changing in the age of AI.
This talk explores what actually breaks in production: ambiguity, hallucinations, and the challenge of mapping natural language to real business logic. It offers a practical look at turning LLM demos into reliable, production-ready systems.... Read more
AI agents often make unnecessary LLM calls, process excessive context, and invoke expensive tools more frequently than needed. In this talk, I'll demonstrate practical techniques that can dramatically reduce operating costs while maintaining user experience and reliability. ... Read more
We ship voice AI agents to regulated industries - healthcare, finance, insurance. Traditional CI/CD breaks when your deployable isn't just code but also prompts, voice configs, and agent behavior definitions. We use GitHub Agentic Workflows as an orchestration layer where AI agents gate, review, and validate other AI agents before they go live. This talk covers the system we built, what broke in production, and what governance looks like when LLMs are making merge decisions for voice AI deployments.... Read more
The talk discusses the question whether agents can serve in roles of data teams, such as Data Engineer / Scientist / Analyst. While addressing the core questions, it gives practical insights what is needed to extract the most value out of your agent setup, with practical examples and implications for your stack. We will also cover the central topics of evaluation and validation.... Read more
It’s 3:45 AM, and you get paged. Still half asleep, you reach for your laptop. Turns out something is wrong, so you acknowledge the incident and embark on a journey to figure out what is happening, mobilize the right people, and eventually fix the issue. But what if we could make it easier? In this talk, I’ll show how AI agents can help you fast-track triage, coordinate responses, debug problems, and run fixes. To wrap up, I will show how we can go even further and move from merely reacting to incidents to proactively preventing them. In the spirit of shifting left, let’s understand how we can track future incidents our code may cause, right before we commit it!... Read more
What does a fully generative video‑game look like when the entire interaction surface is a language model? In this talk I present the first proof‑of‑concept of an Agentic Video‑Game, a 3‑D multiplayer world where every NPC, quest, and environment reaction is driven by LLM‑powered agents.
By wiring the right architectural layers-state‑centric management, event‑driven orchestration, and a lightweight RAG pipeline that injects lore on demand - we turned a concept into a running prototype that has never been demonstrated before.
I will walk through the design decisions that made the system reliable, showcase the live demo, and dive deep into the challenges and lessons learned while stitching together generative AI, real‑time state sync, and production‑grade robustness.... Read more
Somewhere right now, a support chatbot is confidently telling a customer about a product that was discontinued six months ago. The model is fine. The vector database is fine. The batch job that feeds it just hasn’t run yet.
After spending over a decade building high-throughput Kafka and Debezium pipelines for production environments, watching teams bolt state-of-the-art LLMs onto fragile, legacy batch infrastructure is becoming a recognizable and entirely avoidable anti-pattern.
This talk explores Change Data Capture (CDC) as the missing data layer for RAG applications. We will look beyond the whiteboard to see what a real Debezium-to-Kafka-to-LLM pipeline actually looks like, how to handle embeddings in flight, and what breaks in production. The data streaming world solved the stale data problem years ago; it is time we bring those mature, event-driven patterns into the modern AI stack.... Read more
The talk is based on his current project: a Teacher Panel for a German language school. The goal of the app is to help teachers run live Zoom lessons with less switching between Word documents, lesson materials, Zoom chat, vocabulary notes, links, and post-lesson Telegram messages. The main idea of the talk would be that AI should not be the starting point of a product. The starting point should be the real workflow, user constraints, and business value.
AI should not be the starting point of a product. The starting point should be the real workflow, user constraints, and business value. In this project, he carefully uses AI only where it actually supports the teacher—for example, vocabulary support, translations, grammar hints, or lesson preparation—while keeping teacher review and manual approval as core product principles.
Points to be covered:
* discovering real teacher workflows and pain points;
* turning DOCX-based methodology files into a structured live lesson panel;
* separating teacher-only guidance from student-facing material;
* designing safe copy/send workflows for Zoom and Telegram;
* deciding where LLMs add value and where classic automation is better;
* architecture and implementation lessons from building a practical AI-enabled MVP.
This talk could be useful for engineers and technical leaders because it focuses not on adding AI everywhere, but on designing AI-enabled tools around real users, reliability, trust, and production constraints.
Vibe coding and AI tools make implementation faster, but they do not replace product thinking: understanding users, discovering real pain points, validating value, and deciding what should not be automated.... Read more
RAG systems are easy to demo but hard to make reliably useful. The gap between prototype and real performance is rarely the model, but context quality. Retrieval, chunking, ranking, and context construction shape system behavior, and weaknesses in these layers lead to irrelevant answers, poor grounding, and overconfident outputs, even with strong models.
This talk explores practical ways to improve RAG systems: better retrieval signals, cleaner context assembly, noise reduction, and aligning context with user intent.... Read more
How can we better understand the vast complexity of the human genome?
Personalized medicine requires a deep understanding of the genetic code in order to specifically detect and treat diseases. Nevertheless, large parts of the human genome remain, to date, not understood.
To address this challenge, we developed Genolator - a multimodal AI system designed to bridge genetic code and human understanding.
By integrating genomic sequence representations, protein structure information, and natural language models, Genolator allows researchers to query coding sequences in natural language and explore potential biological processes, molecular functions, and cellular roles associated with a sequence.
This ability to connect diverse biological layers through natural language queries creates a new interface for exploring genomic data, helping researchers and physicians uncover functional relationships and generate new insights into the genome.... Read more
Large Language Models routinely suffer from calibration issues, confidently asserting falsehoods when faced with out-of-distribution tasks. Traditional calibration methods often rely on heavy post-hoc tuning or fragile prompt engineering. In this talk, we explore a more dynamic approach: Self-Calibrating Language Models via Test-Time Discriminative Distillation.We will dive into how we can leverage the "generation-discrimination gap" to train models to double-check themselves on the fly. By utilizing lightweight parameter updates (via LoRA) on late transformer layers during the inference phase, we can align a model's verbalized confidence with its underlying discriminative signals ($P(\text{True})$). Finally, we will discuss the practical engineering trade-offs of this approach, including how to implement entropy-based gating mechanisms to manage computational overhead, making self-calibration viable for real-world deployment.... Read more
The LLM in your pipeline is a brilliant intern with no memory and too much confidence and somehow it's in production. A talk about engineering for an LLM you don't trust, with stories from building with LLMs and the tools we ship around them. Bring your paranoia.... Read more
17:00
Wrap up
Scan each other's QR codes & head to a nearby pub!
This talk explores what actually breaks in production: ambiguity, hallucinations, and the challenge of mapping natural language to real business logic. It offers a practical look at turning LLM demos into reliable, production-ready systems.
Bio
Sameer Aman is a Senior Full Stack Engineer based in Hamburg, Germany, currently with 1KOMMA5°. He specializes in building clean, scalable, and user-focused systems across frontend and backend environments. His background includes roles at Wunder Mobility and earlier product leadership positions in India. Sameer’s core strengths include software architecture, Domain-Driven Design, CI/CD, and full stack development, with a reputation for ownership, collaboration, and delivering high-quality engineering solutions.
John Robert
Sunnic Lighthouse GmbH
How to cut AI agent cost
Abstract
AI agents often make unnecessary LLM calls, process excessive context, and invoke expensive tools more frequently than needed. In this talk, I'll demonstrate practical techniques that can dramatically reduce operating costs while maintaining user experience and reliability.
Bio
John Robert leads data and cloud projects at Sunnic Lighthouse (Enerparc AG), where he works on building and operating data-intensive workflows in production. He has over eight years of experience with Python, machine learning, and AI, and began his career working on autonomous driving systems at Daimler (Mercedes-Benz).
John has spoken at conferences across Europe, the United States, and other regions, sharing practical insights on building, deploying, and operating AI systems in real-world environments. His current focus is on AI safety and AI security, particularly how agentic and autonomous systems can be designed with clear boundaries and controls.
He is the founder of Don’t Fear AI, an initiative aimed at helping people understand how to use AI responsibly and how to build reliable AI systems without hype or unnecessary complexity. John believes in a future where humans and AI systems work together safely and effectively.
Virendra Singh Bhalothia
Kolsetu GmbH
Agentic CI/CD: when your pipeline has opinions
Abstract
We ship voice AI agents to regulated industries - healthcare, finance, insurance. Traditional CI/CD breaks when your deployable isn't just code but also prompts, voice configs, and agent behavior definitions. We use GitHub Agentic Workflows as an orchestration layer where AI agents gate, review, and validate other AI agents before they go live. This talk covers the system we built, what broke in production, and what governance looks like when LLMs are making merge decisions for voice AI deployments.
Bio
Virendra Bhalothia is CTO & Co-Founder at Kolsetu, building compliant voice AI infrastructure for regulated industries in Europe. Previously headed platform engineering at Germany's largest private university - iu.de and served as a Staff Engineer leading multi-disciplinary teams. Based in Hamburg.
Andreas Wagenmann
Independent
Agents as your Data Team - Or Not?
Abstract
The talk discusses the question whether agents can serve in roles of data teams, such as Data Engineer / Scientist / Analyst. While addressing the core questions, it gives practical insights what is needed to extract the most value out of your agent setup, with practical examples and implications for your stack. We will also cover the central topics of evaluation and validation.
Bio
Andreas Wagenmann is a Freelance Consultant with over 13 years of hands-on experience, building solutions with focus on ML / AI, Data and Search. He consulted for clients such as Kroger (USA) and Otto (Germany) and in diverse topics including big data, analytics, offline and online testing, search systems, data-driven optimization, ML, LLM and agent implementations and evaluations.
Daniel Afonso
PagerDuty
Incident Response Reimagined: Accelerating Resolution with AI Agents
Abstract
It’s 3:45 AM, and you get paged. Still half asleep, you reach for your laptop. Turns out something is wrong, so you acknowledge the incident and embark on a journey to figure out what is happening, mobilize the right people, and eventually fix the issue. But what if we could make it easier? In this talk, I’ll show how AI agents can help you fast-track triage, coordinate responses, debug problems, and run fixes. To wrap up, I will show how we can go even further and move from merely reacting to incidents to proactively preventing them. In the spirit of shifting left, let’s understand how we can track future incidents our code may cause, right before we commit it!
Bio
Daniel Afonso is a Senior Developer Advocate at PagerDuty, SolidJS DX team member, Instructor at Egghead.io, and Author of State Management with React Query. Daniel has a full-stack background, having worked with different languages and frameworks on various projects from IoT to Fraud Detection. He is passionate about learning and teaching and has spoken at multiple conferences around the world about topics he loves. In his free time, when he's not learning new technologies or writing about them, he's probably reading comics or watching superhero movies and shows.
Eduardo Pertierra Puche
MaibornWolff GmbH
From Prompt to Play: Creating a Fully Generative Agentic Videogame
Abstract
What does a fully generative video‑game look like when the entire interaction surface is a language model? In this talk I present the first proof‑of‑concept of an Agentic Video‑Game, a 3‑D multiplayer world where every NPC, quest, and environment reaction is driven by LLM‑powered agents.
By wiring the right architectural layers-state‑centric management, event‑driven orchestration, and a lightweight RAG pipeline that injects lore on demand - we turned a concept into a running prototype that has never been demonstrated before.
I will walk through the design decisions that made the system reliable, showcase the live demo, and dive deep into the challenges and lessons learned while stitching together generative AI, real‑time state sync, and production‑grade robustness.
Bio
I am an AI Engineer who has spent the last five years consulting at the forefront of the AI wave. While delivering AI automations for MaibornWolff and the BMW Group, I constantly spin up small projects and PoCs that showcase the power of AI, applying the latest technologies and solid AI‑engineering practices to make solutions deployable and production‑ready. My focus is Agentic Coding—building end‑to‑end AI‑driven workflows that turn experimental ideas into reliable, real‑world systems.
Serhat Kayikci
iC Consult
The Missing Layer: Real-Time AI Context with CDC and Kafka
Abstract
Somewhere right now, a support chatbot is confidently telling a customer about a product that was discontinued six months ago. The model is fine. The vector database is fine. The batch job that feeds it just hasn’t run yet.
After spending over a decade building high-throughput Kafka and Debezium pipelines for production environments, watching teams bolt state-of-the-art LLMs onto fragile, legacy batch infrastructure is becoming a recognizable and entirely avoidable anti-pattern.
This talk explores Change Data Capture (CDC) as the missing data layer for RAG applications. We will look beyond the whiteboard to see what a real Debezium-to-Kafka-to-LLM pipeline actually looks like, how to handle embeddings in flight, and what breaks in production. The data streaming world solved the stale data problem years ago; it is time we bring those mature, event-driven patterns into the modern AI stack.
Bio
Serhat Kayikci is a software architect and Senior Consultant at iC Consult in Hamburg, specializing in event-driven architecture, Kafka, and CDC pipelines. With over 15 years of backend engineering experience across enterprise and automotive sectors in Germany, he also operates as an independent infrastructure consultant. Currently bridging the gap between robust backend systems and MLOps, Serhat focuses on the intersection of real-time streaming data and production-ready AI.
Pavlo Borysov
IT-Dienstleistungen K.Rozankovic
From AI Hype to Real User Value: Building a Teacher Cockpit for Live Language Lessons
Abstract
The talk is based on his current project: a Teacher Panel for a German language school. The goal of the app is to help teachers run live Zoom lessons with less switching between Word documents, lesson materials, Zoom chat, vocabulary notes, links, and post-lesson Telegram messages. The main idea of the talk would be that AI should not be the starting point of a product. The starting point should be the real workflow, user constraints, and business value.
AI should not be the starting point of a product. The starting point should be the real workflow, user constraints, and business value. In this project, he carefully uses AI only where it actually supports the teacher—for example, vocabulary support, translations, grammar hints, or lesson preparation—while keeping teacher review and manual approval as core product principles.
Points to be covered:
* discovering real teacher workflows and pain points;
* turning DOCX-based methodology files into a structured live lesson panel;
* separating teacher-only guidance from student-facing material;
* designing safe copy/send workflows for Zoom and Telegram;
* deciding where LLMs add value and where classic automation is better;
* architecture and implementation lessons from building a practical AI-enabled MVP.
This talk could be useful for engineers and technical leaders because it focuses not on adding AI everywhere, but on designing AI-enabled tools around real users, reliability, trust, and production constraints.
Vibe coding and AI tools make implementation faster, but they do not replace product thinking: understanding users, discovering real pain points, validating value, and deciding what should not be automated.
Bio
Pavlo Borysov is a Machine Learning / AI Engineer based in Hamburg, with a background in software engineering, business intelligence, data engineering, and enterprise process automation. He has led software and BI teams in large organizations and currently focuses on practical AI/ML engineering, LLM-based applications, data-driven automation, and integrating AI-enabled tools into real business workflows. His recent work includes AI assistants, workflow automation, API-based integrations, and product-oriented tools for education and business processes.
Mesut Ayata
Thoughtworks
RAG Beyond the Demo: Why Context Matters More Than Models
Abstract
RAG systems are easy to demo but hard to make reliably useful. The gap between prototype and real performance is rarely the model, but context quality. Retrieval, chunking, ranking, and context construction shape system behavior, and weaknesses in these layers lead to irrelevant answers, poor grounding, and overconfident outputs, even with strong models.
This talk explores practical ways to improve RAG systems: better retrieval signals, cleaner context assembly, noise reduction, and aligning context with user intent.
Bio
Mesut has been in IT for around two decades, and currently working as Principal Data Architect at Thoughtworks. He served in different roles leading multiple cross functional teams and technical leads with experience in Mobility, Automotive, Digital Transformation and more areas with a wide range of technology stack from on-prem to cloud solutions, architecture and modern development practices.
Martin Danner
scieneers GmbH
Talk Genomics To Me - From Sequences to Sentences
Abstract
How can we better understand the vast complexity of the human genome?
Personalized medicine requires a deep understanding of the genetic code in order to specifically detect and treat diseases. Nevertheless, large parts of the human genome remain, to date, not understood.
To address this challenge, we developed Genolator - a multimodal AI system designed to bridge genetic code and human understanding.
By integrating genomic sequence representations, protein structure information, and natural language models, Genolator allows researchers to query coding sequences in natural language and explore potential biological processes, molecular functions, and cellular roles associated with a sequence.
This ability to connect diverse biological layers through natural language queries creates a new interface for exploring genomic data, helping researchers and physicians uncover functional relationships and generate new insights into the genome.
Bio
Martin Danner is a Senior Data Scientist and Machine Learning Engineer at scieneers, where he designs and builds scalable AI systems and cloud-based data platforms for organizations across industries including healthcare, energy, media, construction, and the public sector. His work focuses on bringing machine learning into production, spanning data engineering, cloud architecture, MLOps, and the deployment of large-scale AI systems.
Alongside his industry work, he is pursuing a PhD at the Centre for Human Genetics and Genomic Medicine at RWTH Aachen University Hospital. His research explores the use of machine learning, genomic language models, and large language models to better understand previously understudied regions of the human genome, sometimes referred to as the “dark genome,” with applications ranging from variant interpretation to protein structure prediction and microprotein research.
Working at the intersection of AI engineering, cloud platforms, and biomedical research, Martin regularly speaks about building AI infrastructure, deploying machine learning systems in production, and applying AI in genomics and healthcare.
Rissal Hedna
PHAROS Labs
Beyond Prompting: Self-Calibrating LLMs via Test-Time Discriminative Distillation
Abstract
Large Language Models routinely suffer from calibration issues, confidently asserting falsehoods when faced with out-of-distribution tasks. Traditional calibration methods often rely on heavy post-hoc tuning or fragile prompt engineering. In this talk, we explore a more dynamic approach: Self-Calibrating Language Models via Test-Time Discriminative Distillation.We will dive into how we can leverage the "generation-discrimination gap" to train models to double-check themselves on the fly. By utilizing lightweight parameter updates (via LoRA) on late transformer layers during the inference phase, we can align a model's verbalized confidence with its underlying discriminative signals ($P(\text{True})$). Finally, we will discuss the practical engineering trade-offs of this approach, including how to implement entropy-based gating mechanisms to manage computational overhead, making self-calibration viable for real-world deployment.
Bio
Rissal Hedna is an AI Engineer at Pharos Labs and a Language AI Researcher specializing in Large Language Model (LLM) calibration, alignment, and parameter-efficient fine-tuning. Working on model reliability, and co-creator of SECL, a novel test-time training framework designed to stop LLMs from confidently lying by forcing them to self-calibrate during inference. Attempting to find direct links between deep machine learning theory and production-ready engineering, he focuses on building AI systems that are mathematically sound, computationally efficient, and safe for critical-domain deployment.
Mohamed Badawi
Weaviate
Engineering for an LLM you don't trust
Abstract
The LLM in your pipeline is a brilliant intern with no memory and too much confidence and somehow it's in production. A talk about engineering for an LLM you don't trust, with stories from building with LLMs and the tools we ship around them. Bring your paranoia.
Bio
Founder of Anonde, open-source data protection for LLM pipelines. Distrusts LLMs professionally.
18+ years in tech with a focus on distributed systems. Background includes Weaviate, HashiCorp, and a decade of earlier startups.